Sitemap
A list of all the posts and pages found on the site. For you robots out there is an XML version available for digesting as well.
Pages
Posts
Growing amount of pesticide/weedicide use in agriculture across the world
Published:
Increasing human population across the world has raised demands for food productions. And this is exerting pressure on both agriculture as well as meat industries. The growing food demand has subsequntly increased demands for required input materials, like seeds, fertilizers (including pesticide and weedicides).
Data Science in Ecology
Published:
Let me introduce a part of ecological studies which uses various modeling methods used and now prominent/useful in data-driven modeling. This blog is simply to motivate, why data science has become a widely used tool in ecological studies. I will discuss the pros of such modeling techniques and try to set baselines with various terminologies used in the domain.
Blog Post number 4
Published:
This is a sample blog post. Lorem ipsum I can’t remember the rest of lorem ipsum and don’t have an internet connection right now. Testing testing testing this blog post. Blog posts are cool.
Blog Post number 3
Published:
This is a sample blog post. Lorem ipsum I can’t remember the rest of lorem ipsum and don’t have an internet connection right now. Testing testing testing this blog post. Blog posts are cool.
portfolio
Journeys Through Pages: A Passion for Book Reading
Published:
Through a love for books, boundless worlds unfold, wisdom flows like a deep wellspring, and pages whisper secrets of lives beyond the familiar. !! 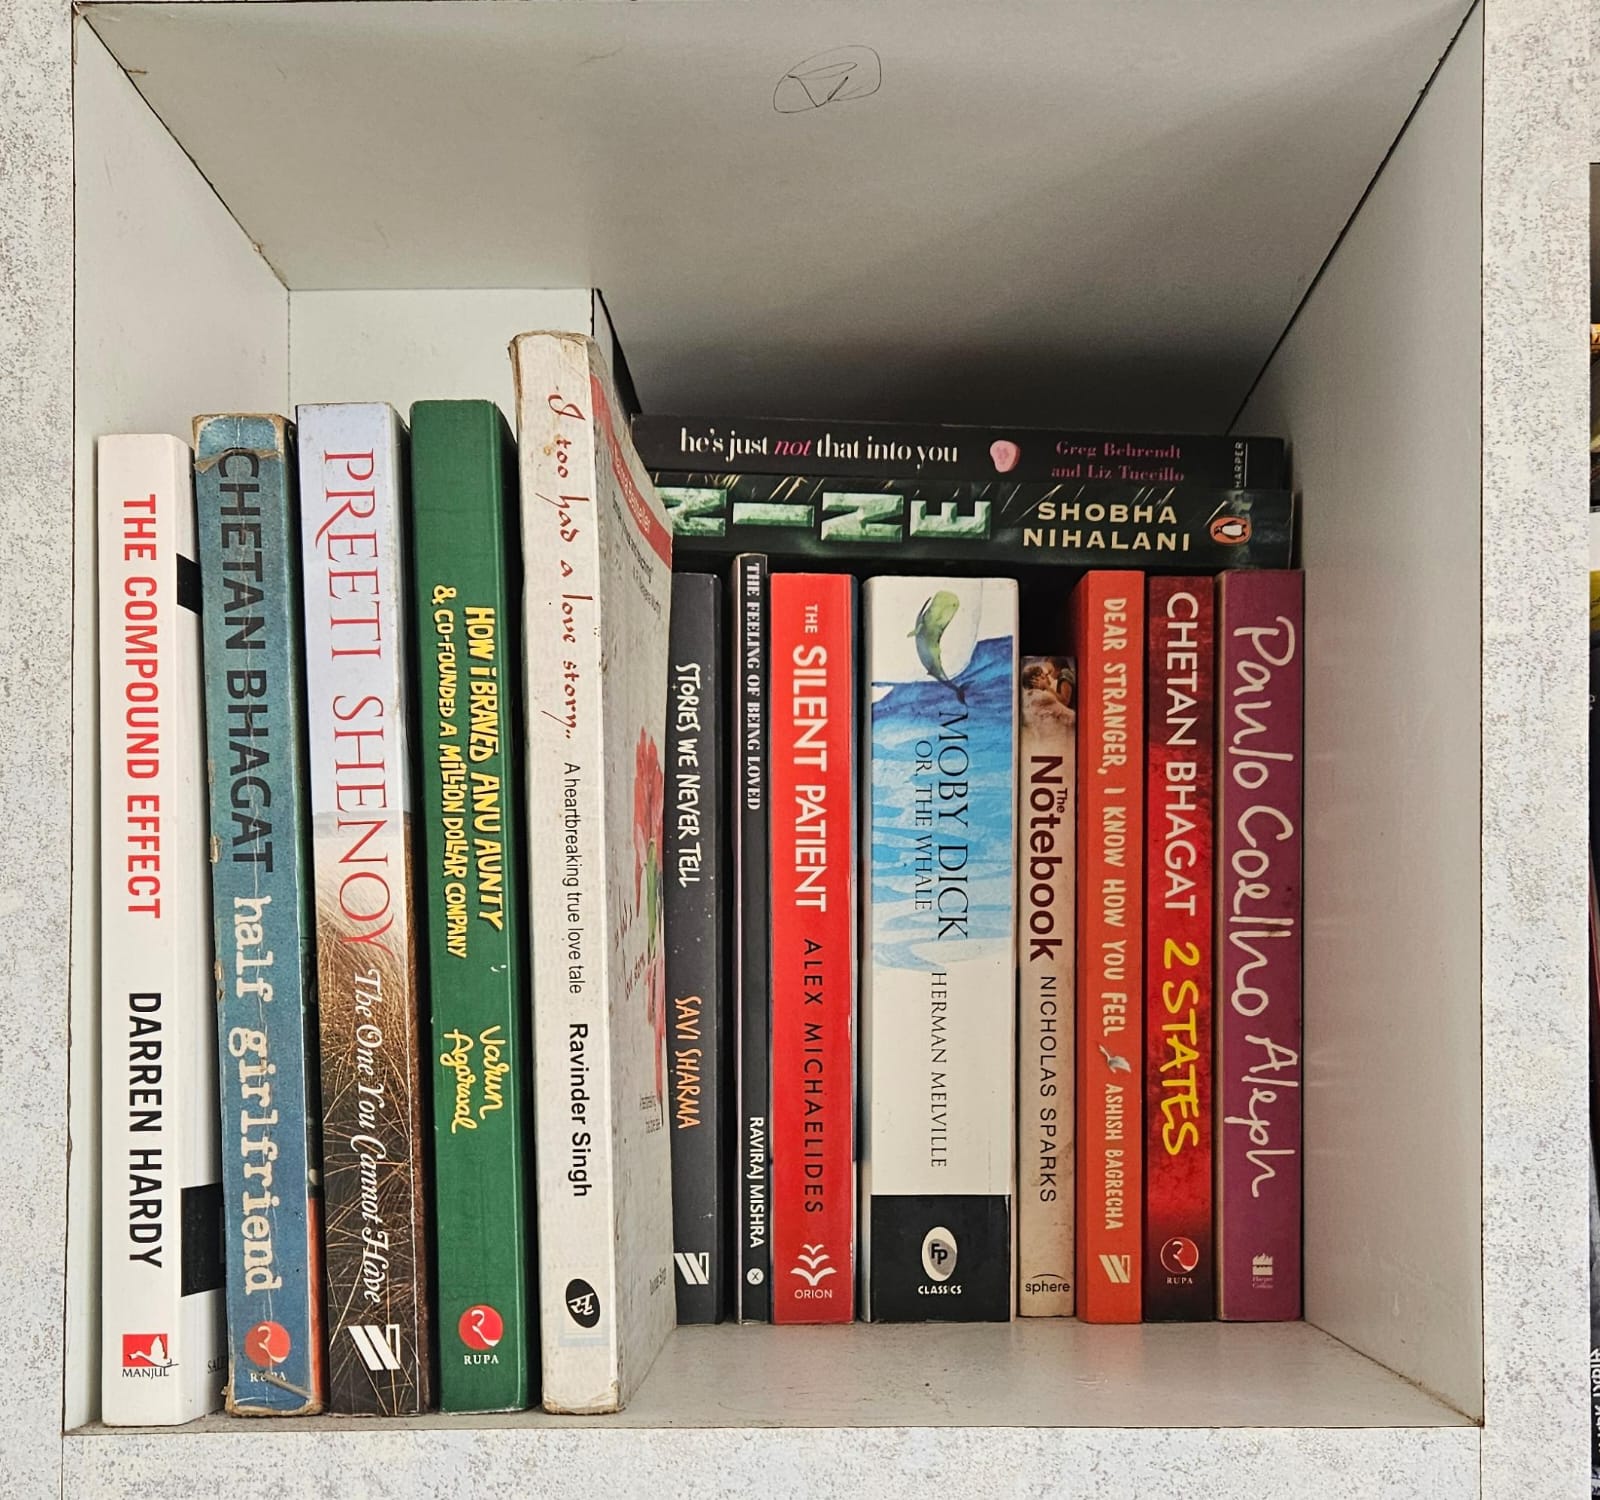
Wanderlust: Adventure awaits everywhere…
Published:
Travel opens minds and leaves memories, showing us the world’s endless stories. 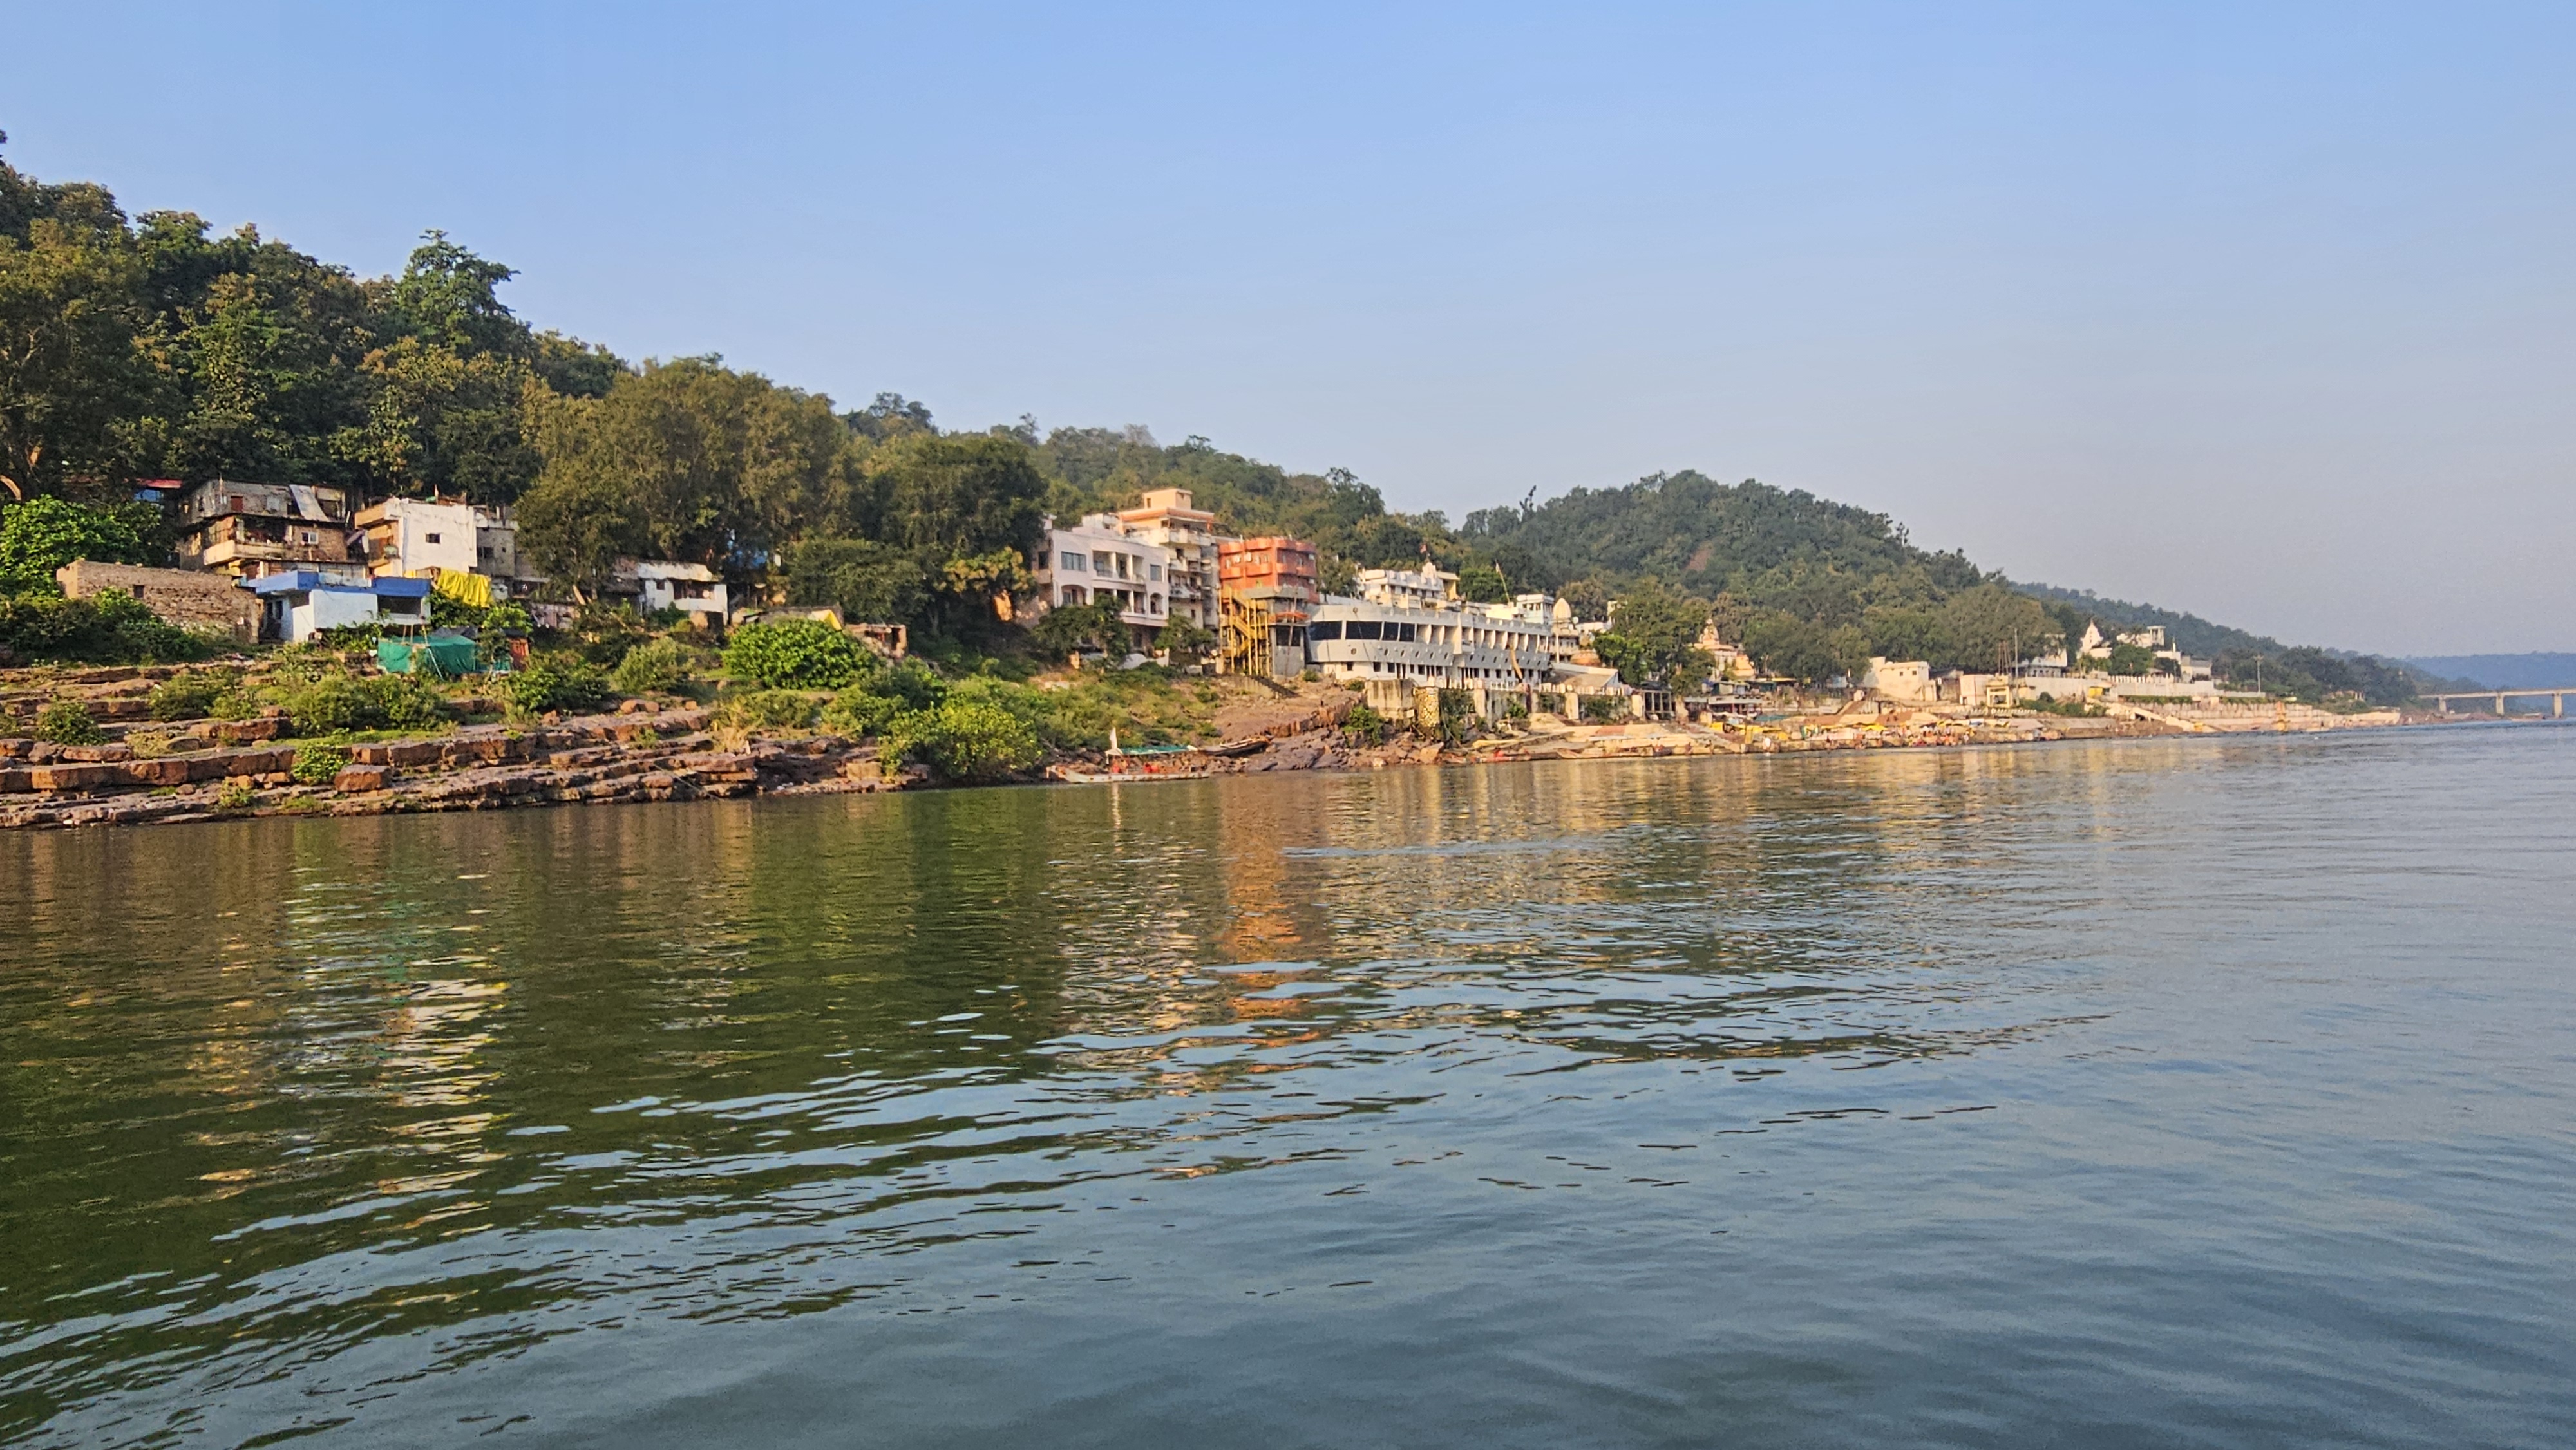
Weekly Trekking Routine
Published:
Daybreak: The dawn unwraps its golden hue, as morning sun spills light anew. !! 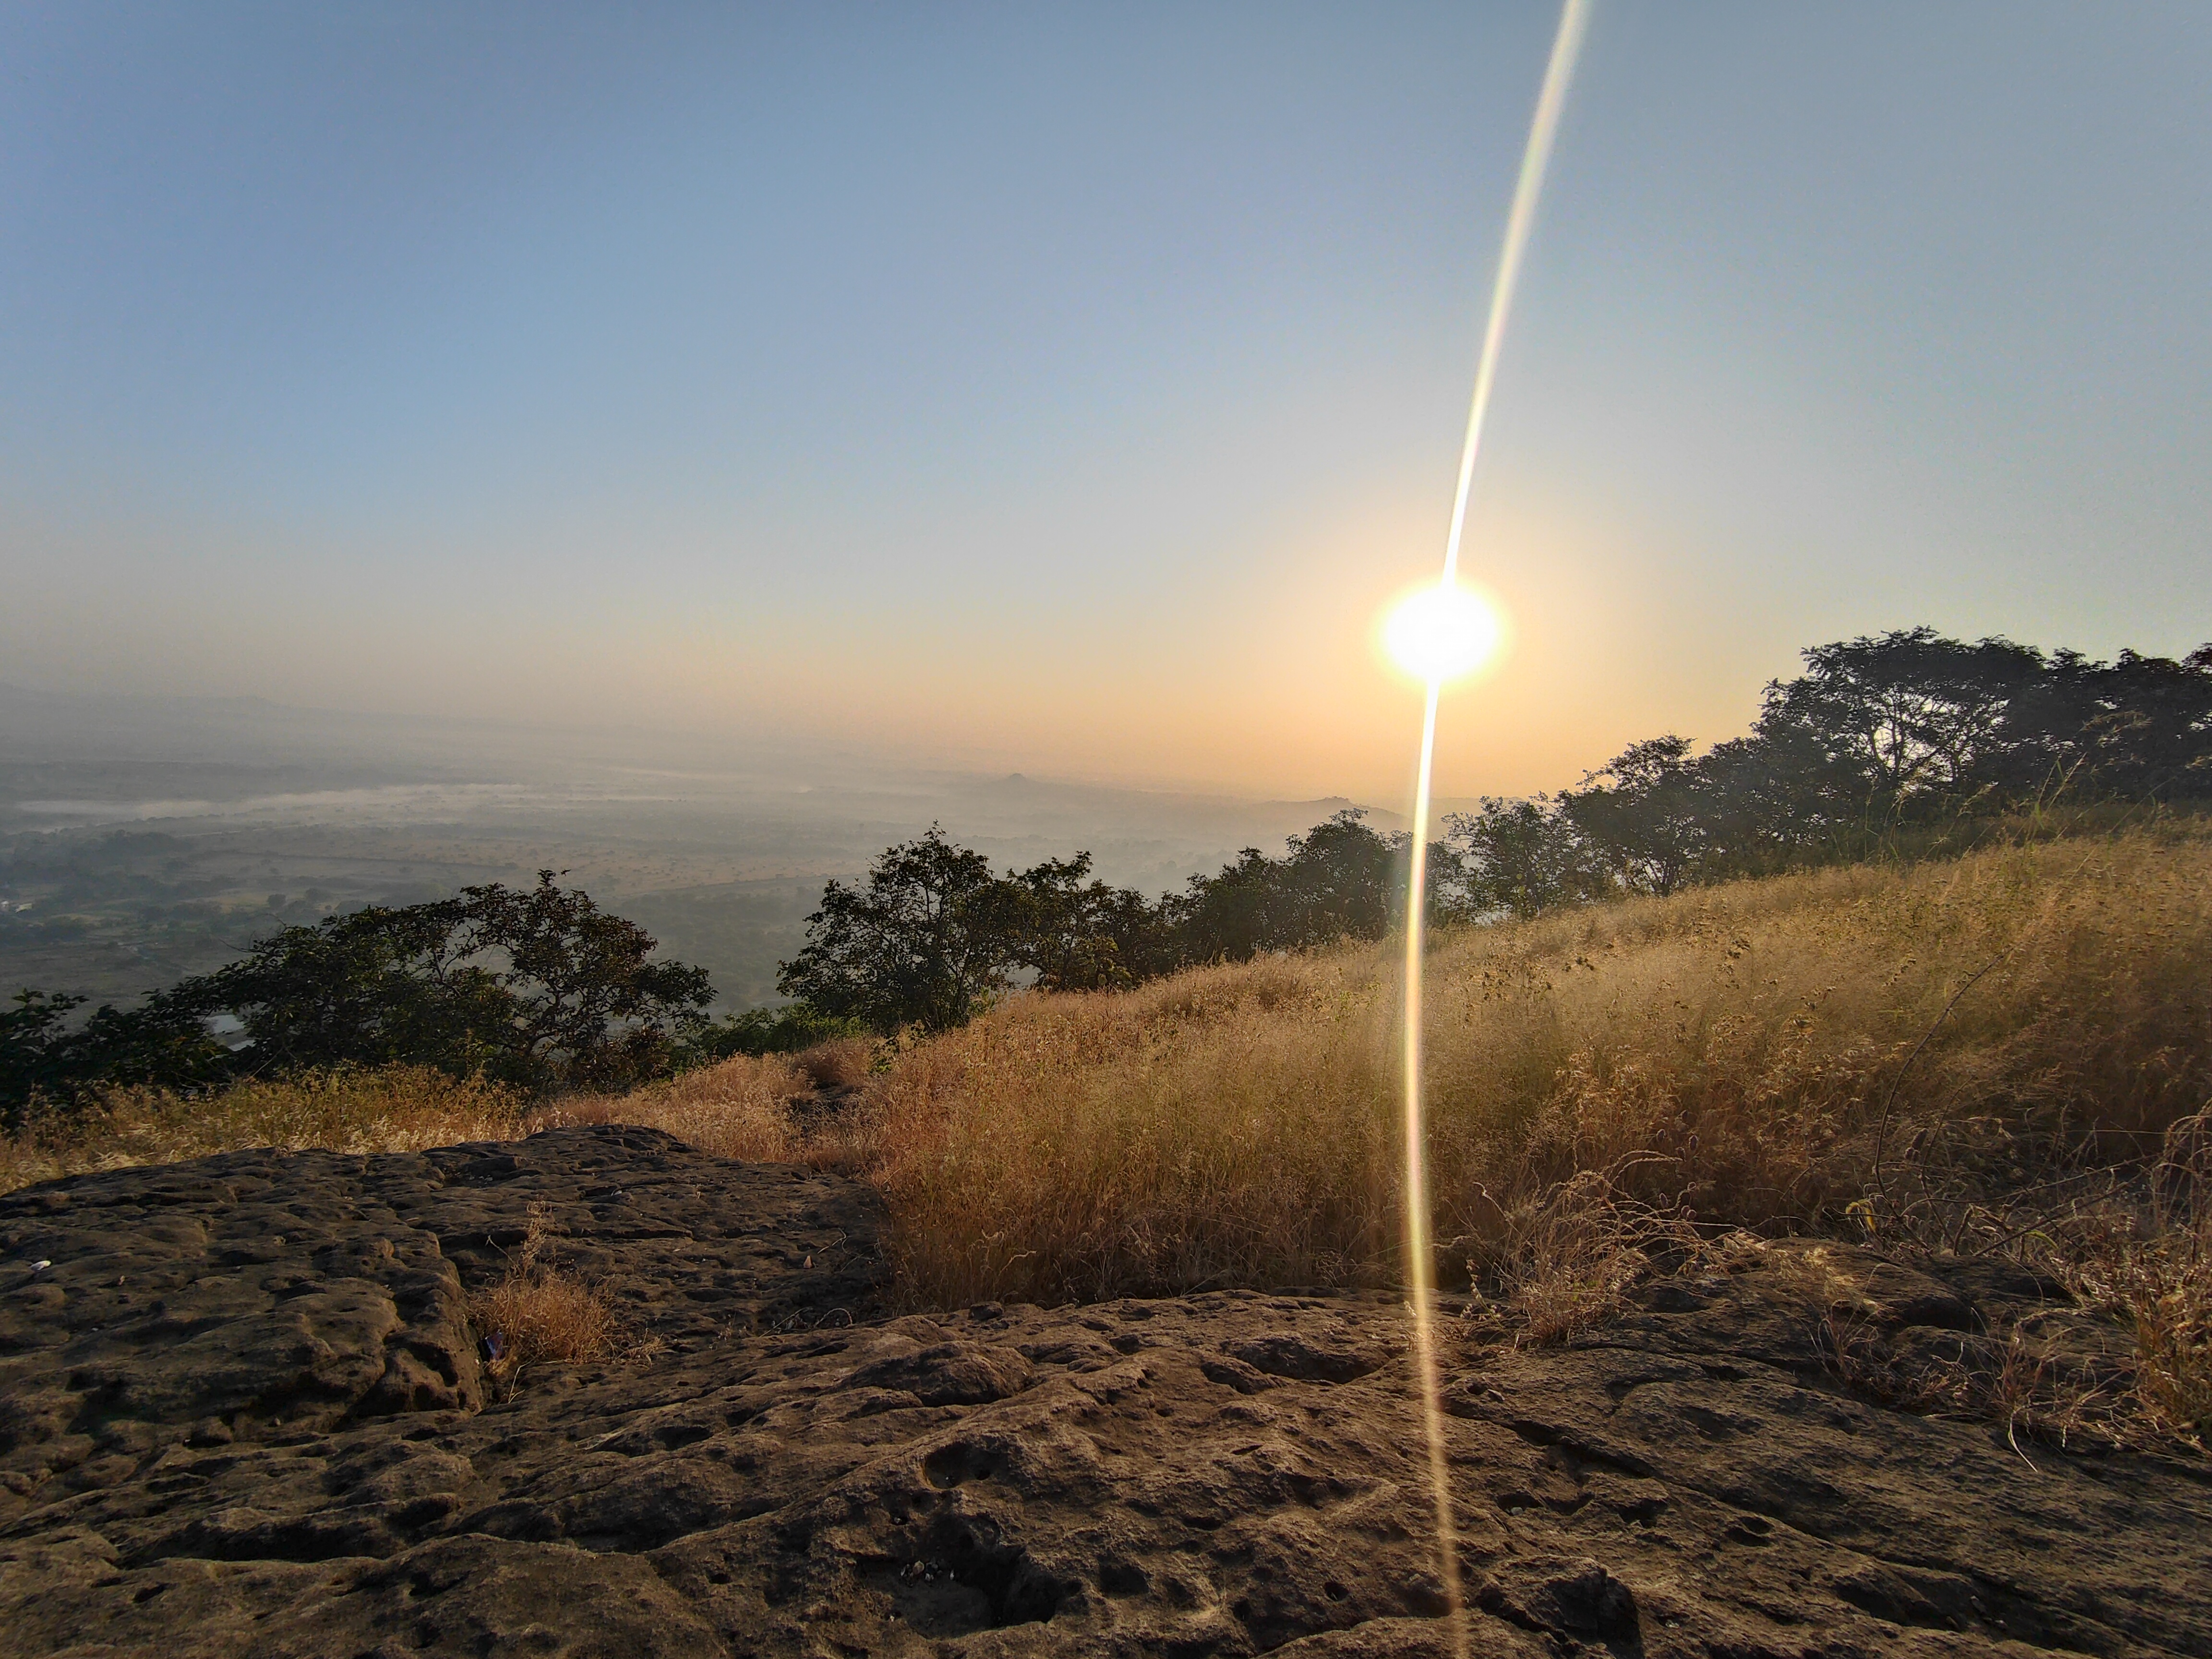
projects
Feature Selection for Multi-label dataset Permalink
Published:
Reducing multi-label dataset dimensionality through feature selection. Utilizing filter methods like Multilabel Informed Feature Selection, Robust Feature Selection, and Mutual Information
Detection of specific antibodies/allergens using Machine Learning
Published:
Collaboration with Bioinformatics Centre, Pune University. From AllerBase, a comprehensive knowledge base of allergens. Classification of allergen-related features such as IgG, IgM, IgA, and IgE using Machine Learning. Research paper contribution
Loan Prediction Competition by Analytics Vidhya
Published:
Given imbalanced dataset for prediction of whether a person will get a loan or not for which they have applied. Used ML models with EDA, feature selection & engineering, Data Imbalance techniques, Grid search, etc. Rank: 15/81895 Accuracy : 82.638%
Ayurveda Prakriti Classification using Machine Learning
Published:
Collaboration with C-DAC, Pune University Campus. Applying Machine Learning for Ayurveda Prakriti (Dosha) Classification. Addressing it as a Multi-class and Multi-label problem.
WNS Analytics Wizard 2018
Published:
Predict whether a potential promotee at checkpoint will be promoted or not after the evaluation process. Used ML models with EDA, feature selection, Data Imbalance techniques (Imbalance ratio: 92:8), Grid search, etc.
Forecast Indian summer monsoon rainfall using ensemble techniques
Published:
Collaboration with Indian Institute of Tropical Meteorology (IITM), Pune. Using ensemble techniques of Machine Learning for prediction of Indian summer monsoon rainfall.
Classification of atomic clusters using Machine learning
Published:
Collaboration with CSIR-National Chemical Laboratory, Pune: Machine Learning-based classification of atomic clusters of Gallium considering shape, atomic distances, and geometrical properties. Utilizing both supervised and unsupervised Machine Learning methods.
StumbleUpon Evergreen Classification Challenge Permalink
Published:
Built a classifier which will evaluate a large set of URLs and label them as either evergreen or ephemeral. Used EDA, Text Data Preprocessing, Word Embedding, Feature engineering, Machine Learning models such as CatBoost and Logistic regression, Deep Learning models such as LSTM and BERT
Toxic Comment Classification Challenge Permalink
Published:
Built a multi-label model which is capable of accurately detecting different types of toxicity like threats, obscenity, insults, and identity-based hate from comments made on social media posts. Used Data Transformation strategies such as Binary relevance, Label PowerSet, Classifier Chains and RaKel to solve multi-label problem. Used EDA, Text Data Preprocessing, Word Embedding, and Machine Learning models such as XGBoost and Logistic regression. Deep Learning models such as LSTM, and BERT.
Hybrid Retrieval Architecture Permalink
Published:
- Designed a hybrid retrieval pipeline combining sparse retrieval (BM25) and dense embedding-based search to improve document recall and ranking accuracy.
- Implemented vector search infrastructure using FAISS for efficient similarity search over large document collections.
- Integrated cross-encoder re-ranking models to improve final document ranking quality for downstream LLM tasks.
- Optimized chunking strategies and embedding generation for better semantic retrieval performance.
- Demonstrated improvements in retrieval accuracy and contextual relevance for knowledge-intensive LLM applications.
LLM-based Scientific Question Answering Permalink
Published:
- Built a knowledge-grounded question-answering system using Wikipedia corpus and transformer-based language models.
- Implemented a RAG pipeline combining document retrieval, re-ranking, and LLM answer generation.
- Applied hybrid retrieval and contextual re-ranking techniques to improve answer accuracy and reduce hallucinations.
- Designed preprocessing pipelines for document chunking, indexing, and metadata management.
- Evaluated system performance using curated datasets and automated evaluation metrics for scientific knowledge queries.
RAG Evaluation Framework Permalink
Published:
- Designed a comprehensive evaluation framework for Retrieval-Augmented Generation (RAG) systems to assess retrieval relevance, answer faithfulness, and hallucination rates.
- Built automated pipelines to evaluate retrieval quality using metrics such as context precision, recall, and ranking performance.
- Implemented LLM-based evaluation techniques for answer grounding, factual consistency, and response completeness.
- Developed benchmarking workflows to compare different retrievers, chunking strategies, and embedding models.
- Enabled systematic experimentation and monitoring to improve reliability of production RAG applications.
Scalable LLM Systems Permalink
Published:
- Developed scalable infrastructure for high-throughput LLM inference and deployment.
- Optimized model serving pipelines using efficient batching, token scheduling, and inference optimization techniques.
- Designed architecture capable of supporting multiple concurrent users and high request volumes.
- Integrated vector databases, retrieval pipelines, and LLM inference components into end-to-end AI applications.
- Built monitoring and evaluation pipelines to ensure performance, scalability, and reliability of production LLM systems.
Enterprise Customer Support AI Platform Permalink
Published:
Routing a support ticket correctly, finding the right answer, and executing account actions safely are three problems that most systems solve in isolation. This project treats them as one pipeline. A LangGraph agent classifies intent using one of 15 trained scikit-learn models, retrieves context through a hybrid BM25 and pgvector search, applies deterministic policy rules, and routes high-risk operations to human approvers. The data foundation is 1,000 support tickets across four channels and 90 knowledge documents chunked into 185 passages. Full architecture and benchmarks in project_overview.md.
Interactive Visualization for Algorithms Permalink
Published:
Interactive Streamlit apps for visualizing how stochastic optimization and machine learning algorithms behave — built to make the mechanics tangible instead of abstract.
publications
A Simple Method of Solution For Multi-label Feature Selection
Published in IEEE International Conference on Electrical, Computer and Communication Technologies, 2019
Multi-label classification problems suffer from an exponentially large label space, making feature selection computationally expensive. This paper proposes a two-step approach: first compress the label space into a lower-dimensional representation, then run feature selection within that reduced space. The method significantly cuts computational cost while retaining predictive accuracy on high-dimensional benchmark datasets.
Recommended citation: Valadi, Jayaraman K., Prasad T. Ovhal, and Kunal J. Rathore. "A simple method of solution for multi-label feature selection." 2019 IEEE International Conference on Electrical, Computer and Communication Technologies (ICECCT). IEEE, 2019. https://ieeexplore.ieee.org/document/8869493
Twin and multiple black holes algorithm for feature selection
Published in 2020 IEEE-HYDCON., 2020
The standard Black Hole algorithm uses a single attractor to guide the search, which can limit diversity and cause premature convergence. This paper introduces Twin and Multiple Black Hole variants that maintain several competing attractors simultaneously, improving exploration of the feature space. Paired with an SVM classifier, the new variants outperform the original algorithm on feature subset quality and classification accuracy.
Recommended citation: P. T. Ovhal, J. K. Valadi and A. Sane, "Twin and Multiple Black Holes Algorithm for Feature Selection," 2020 IEEE-HYDCON, Hyderabad, India, 2020, pp. 1-6, doi: 10.1109/HYDCON48903.2020.9242882. https://ieeexplore.ieee.org/abstract/document/9242882
Random forest and autoencoder data-driven models for prediction of dispersed-phase holdup and drop size in rotating disc contactors
Published in Industrial & Engineering Chemistry Research, 2020
Accurate prediction of dispersed-phase holdup and drop size is essential for designing and scaling rotating disc contactors (RDCs) used in chemical extraction processes — yet the underlying relationships are highly nonlinear and poorly captured by classical regression. This paper applies Random Forest (RF) and an autoencoder-augmented RF to these prediction tasks. The standalone RF generalizes well across both targets; the autoencoder combination improves drop size prediction but offers limited benefit for holdup. The work demonstrates that data-driven ML models are a viable replacement for physics-based correlations in chemical engineering design.
Recommended citation: Swetha Saraswathi K., Hrushikesh Bhosale, Prasad Ovhal, Naren Parlikkad Rajan, and Jayaraman Krishnamoorthy Valadi Industrial & Engineering Chemistry Research 2021 60 (1), 425-435 DOI: 10.1021/acs.iecr.0c04149 https://pubs.acs.org/doi/abs/10.1021/acs.iecr.0c04149
Black Hole—White Hole algorithm for dynamic optimization of chemically reacting systems
Published in Congress on Intelligent Systems: Proceedings of CIS 2020, Volume 2, 2021
Dynamic optimization of chemical reactors — finding optimal control profiles over time to maximize yield or minimize cost — is a difficult problem that conventional solvers struggle with due to non-convexity and sensitivity to initial conditions. This paper extends the Black Hole algorithm by introducing a White Hole component that counterbalances the algorithm’s exploitation tendency with active exploration, preventing the search from stagnating in local optima. Tested on benchmark chemical reaction systems using both piecewise linear and piecewise constant control profiles, the Black Hole–White Hole algorithm matches or outperforms existing methods while remaining simple to implement.
Recommended citation: Ovhal, P., Valadi, J.K. (2021). Black Hole—White Hole Algorithm for Dynamic Optimization of Chemically Reacting Systems. In: Sharma, H., Saraswat, M., Yadav, A., Kim, J.H., Bansal, J.C. (eds) Congress on Intelligent Systems. CIS 2020. Advances in Intelligent Systems and Computing, vol 1335. Springer, Singapore. https://doi.org/10.1007/978-981-33-6984-9_43 https://link.springer.com/chapter/10.1007/978-981-33-6984-9_43
Improved filter ranking incorporated binary black hole algorithm for feature selection
Published in SN Computer Science, 2022
Pure wrapper-based feature selection methods like Black Hole are computationally effective but ignore the statistical properties of individual features. This paper embeds filter-based rankings — Pearson correlation combined with Gini importance, and Pearson correlation combined with mutual information — directly into the Black Hole algorithm’s fitness function, switching between the filter-guided and standard criteria probabilistically during the search. The hybrid strategy produces smaller feature subsets with higher accuracy than the standalone Black Hole algorithm, and performs competitively against a filter-enhanced Ant Colony Optimization baseline across diverse benchmark datasets from science and engineering.
Recommended citation: Ovhal, P., Kulkarni, S. & Valadi, J.K. Improved Filter Ranking Incorporated Binary Black Hole Algorithm for Feature Selection. SN COMPUT. SCI. 3, 51 (2022). https://doi.org/10.1007/s42979-021-00933-w https://link.springer.com/article/10.1007/s42979-021-00933-w
Improving Black Hole Algorithm Performance by Coupling with Genetic Algorithm for Feature Selection
Published in Congress on Intelligent Systems: Proceedings of CIS 2021, Volume 1, 2022
The Black Hole algorithm converges efficiently but can get trapped in local optima; Genetic Algorithms diversify the search well through crossover and mutation but converge slowly. This paper couples both into a single hybrid: a switching probability parameter controls when the algorithm follows Black Hole update rules versus Genetic Algorithm operators, combining the strengths of both. Tuning the switching probability is shown to be key — the optimally configured hybrid yields considerably better feature subsets than either algorithm run independently.
Recommended citation: Bhosale, H., Ovhal, P., Sane, A., Valadi, J.K. (2022). Improving Black Hole Algorithm Performance by Coupling with Genetic Algorithm for Feature Selection. In: Saraswat, M., Sharma, H., Balachandran, K., Kim, J.H., Bansal, J.C. (eds) Congress on Intelligent Systems. Lecture Notes on Data Engineering and Communications Technologies, vol 114. Springer, Singapore. https://doi.org/10.1007/978-981-16-9416-5_26 https://link.springer.com/chapter/10.1007/978-981-16-9416-5_26
Intrusion Detection with Black Hole Feature Selection
Published in Congress on Smart Computing Technologies, 2022
Network intrusion detection datasets are high-dimensional, containing many redundant and noisy features that degrade classifier performance. This paper applies Binary and Real-Coded variants of the Black Hole algorithm to select the most informative feature subsets, evaluated with a Random Forest classifier on three standard intrusion detection benchmarks — NSL-KDD, CIC-IDS2017, and the Aegean Wi-Fi dataset. The Real-Coded variant encodes feature relevance as continuous values rather than hard binary flags, offering finer-grained selection. Both variants outperform conventional feature selection methods, achieving higher detection accuracy with fewer features.
Recommended citation: Kulkarni, S., Ovhal, P., Valadi, J.K. (2023). Intrusion Detection with Black Hole Feature Selection. In: Bansal, J.C., Sharma, H., Chakravorty, A. (eds) Congress on Smart Computing Technologies. CSCT 2022. Smart Innovation, Systems and Technologies, vol 351. Springer, Singapore. https://doi.org/10.1007/978-981-99-2468-4_9 https://link.springer.com/chapter/10.1007/978-981-99-2468-4_9
talks
Stochastic Optimization Methods and Their Applications in Machine Learning
Published:
- Introduced the family of stochastic optimization algorithms and their motivation over classical gradient-based methods for non-convex, high-dimensional search spaces.
- Covered Simulated Annealing — probabilistic hill-climbing inspired by the annealing process in metallurgy, used for combinatorial optimization and hyperparameter search.
- Explained Genetic Algorithms (GA) — population-based evolutionary search using selection, crossover, and mutation operators, applied to feature selection and neural architecture search.
- Presented Ant Colony Optimization (ACO) — swarm intelligence algorithm modeled on foraging behavior, used for routing, scheduling, and graph-based ML problems.
- Detailed the Black Hole Algorithm — a nature-inspired metaheuristic where candidate solutions orbit a best solution (the black hole) and are absorbed if they cross the event horizon, applied to feature subset selection.
- Demonstrated comparative performance of these methods on feature selection benchmarks, showing improvements in model accuracy and dimensionality reduction over filter-based baselines.
Recent Trends in Machine Learning
Published:
- Delivered a webinar on the current state and emerging trends in machine learning and data science.
- Covered the data science lifecycle, essential tools, and the role of visualization in model interpretability.
- Introduced core ML paradigms — supervised, unsupervised, and reinforcement learning — with practical examples.
- Highlighted career pathways in data science, including industry roles, research tracks, and skill-building strategies.
- Engaged students with a live Q&A session on real-world applications and learning resources.
Is Traditional ML Dead?
Published:
- Examined the evolving landscape of machine learning in the era of large language models and foundation models.
- Challenged the narrative that traditional ML is obsolete — argued for its continued relevance in structured data problems, low-latency inference, and resource-constrained environments.
- Discussed when LLMs and generative AI are the right tool versus when classical models (gradient boosting, SVMs, linear models) outperform them in cost, speed, and interpretability.
- Highlighted hybrid architectures that combine traditional ML with LLM components for production systems.
- Addressed practical trade-offs: compute cost, data requirements, explainability, and regulatory compliance that keep traditional ML indispensable.
JIRA AI: Native Features and Building Custom AI Agents for Workflow Automation
Published:
- Delivered a hands-on workshop showcasing JIRA’s native AI capabilities for intelligent issue summarization, sprint planning assistance, and backlog prioritization.
- Demonstrated how to build custom AI agents on top of JIRA’s API to automate repetitive workflow tasks such as ticket triage, assignment routing, and status tracking.
- Walked through end-to-end agent design — tool definitions, task decomposition, and integration with JIRA’s REST API and webhooks.
- Showed live examples of agents automating sprint retrospective summaries and dependency detection across linked issues.
- Covered best practices for prompt engineering, error handling, and safe deployment of AI agents in project management contexts.
Agentic Evaluation: Assessing Autonomous LLM Workflows
Published:
- Presented evaluation frameworks specifically designed for agentic AI systems, where standard NLP metrics fall short of capturing agent behavior.
- Detailed methodologies for assessing agent execution trajectories — evaluating the sequence of steps an agent takes, not just its final output.
- Covered tool-calling accuracy — measuring correctness, relevance, and efficiency of tool selection and parameter construction across multi-step tasks.
- Introduced end-to-end task completion metrics for autonomous LLM workflows, including partial credit scoring and failure mode taxonomy.
- Discussed hallucination risks specific to agentic contexts — compounding errors across tool calls and reasoning chains.
- Shared practical benchmarking setups and open-source frameworks used to evaluate production agentic systems at Red Hat.
teaching
Teaching Associate
Postgraduate course, Flame University, Computing and Data Sciences , 2019
Conducted Data Analytics course with hands-on R as a Teaching Associate with Prof. Jayaraman at Flame University, from July 2019 to Nov 2019.
Teaching Associate
Postgraduate course, Pune University, Centre for Modelling & Simulation , 2019
Conducting lectures on Python & R Hands-on, Data Science, Machine Learning and Stochastic Optimization at Centre for Modeling and Simulation, Pune University. From 2019 to Present
Teaching Associate
Postgraduate course, Pune University, Bioinformatics Department , 2024
Conducted Scientific Data Mining and Visualization & Advanced Algorithms in Machine Learning course with hands-on Python as a Teaching Associate with Prof. Jayaraman at Bioinformatics Department, Pune University, from Aug 2024 to Present
writing
What a Production LLM App Actually Needs Permalink
Published:
Most tutorials show you how to call an LLM. Production is a different problem — latency, cost, hallucination, observability, and trust all show up at once. This article breaks down what it actually takes to ship a reliable LLM application.
Why Top-K Retrieval Is a Design Assumption, Not a Law Permalink
Published:
Top-K retrieval is treated as a default in most RAG pipelines — but it’s an assumption worth questioning. Here’s why it matters and what you can do instead.
Your RAG Recall@5 Is 90% — So Why Are Users Still Getting Wrong Answers? Permalink
Published:
High retrieval metrics don’t guarantee correct answers. This article digs into the gap between retrieval quality and end-user correctness in RAG systems — and what to measure instead.